
Reddit Rate Limit Exceeded: Diagnose and Fix 429 Errors
Oct 9, 2026 · Guides · 12 min read
TL;DR
- Stop the traffic first. Immediate retries add load and destroy useful diagnostic evidence.
- Record the exact message and context. A posting cooldown is not the same as an API 429 or a network-security block.
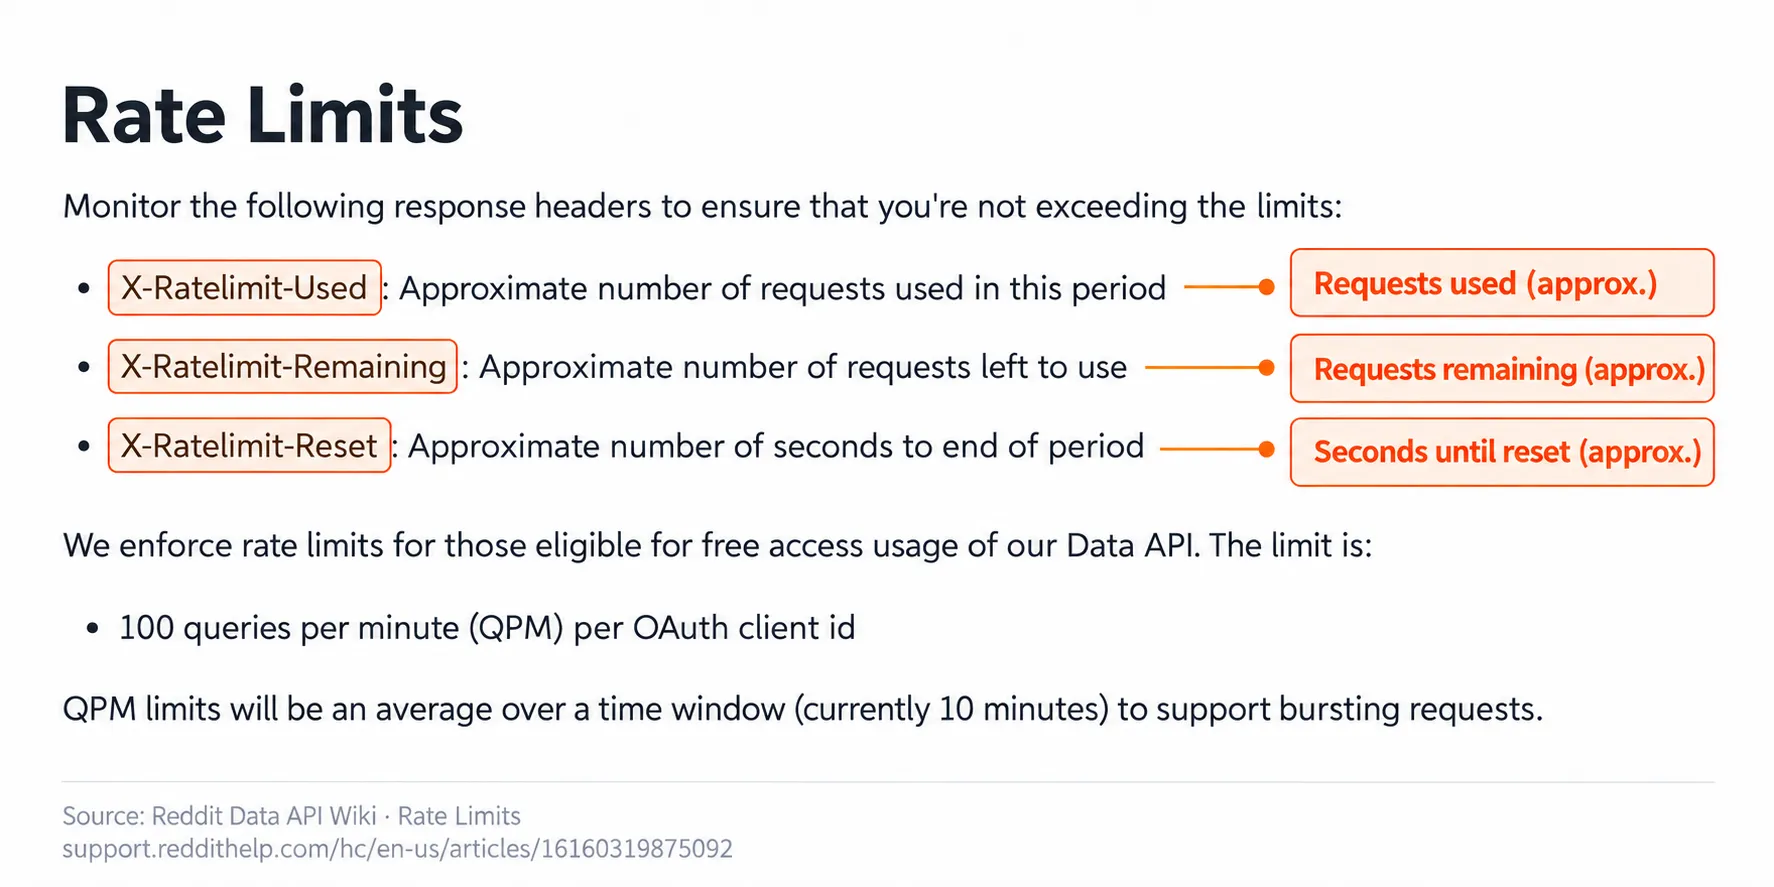
- For Data API calls, use OAuth and read the headers. Track
X-Ratelimit-Used,X-Ratelimit-Remaining, andX-Ratelimit-Resetwhen Reddit returns them. - Treat the budget as shared. Multiple workers using the same OAuth client can exhaust one common allowance.
- Use a proxy only for a separately authorized network-routing need. It cannot expand an OAuth client quota, clear an account cooldown, or grant data rights.
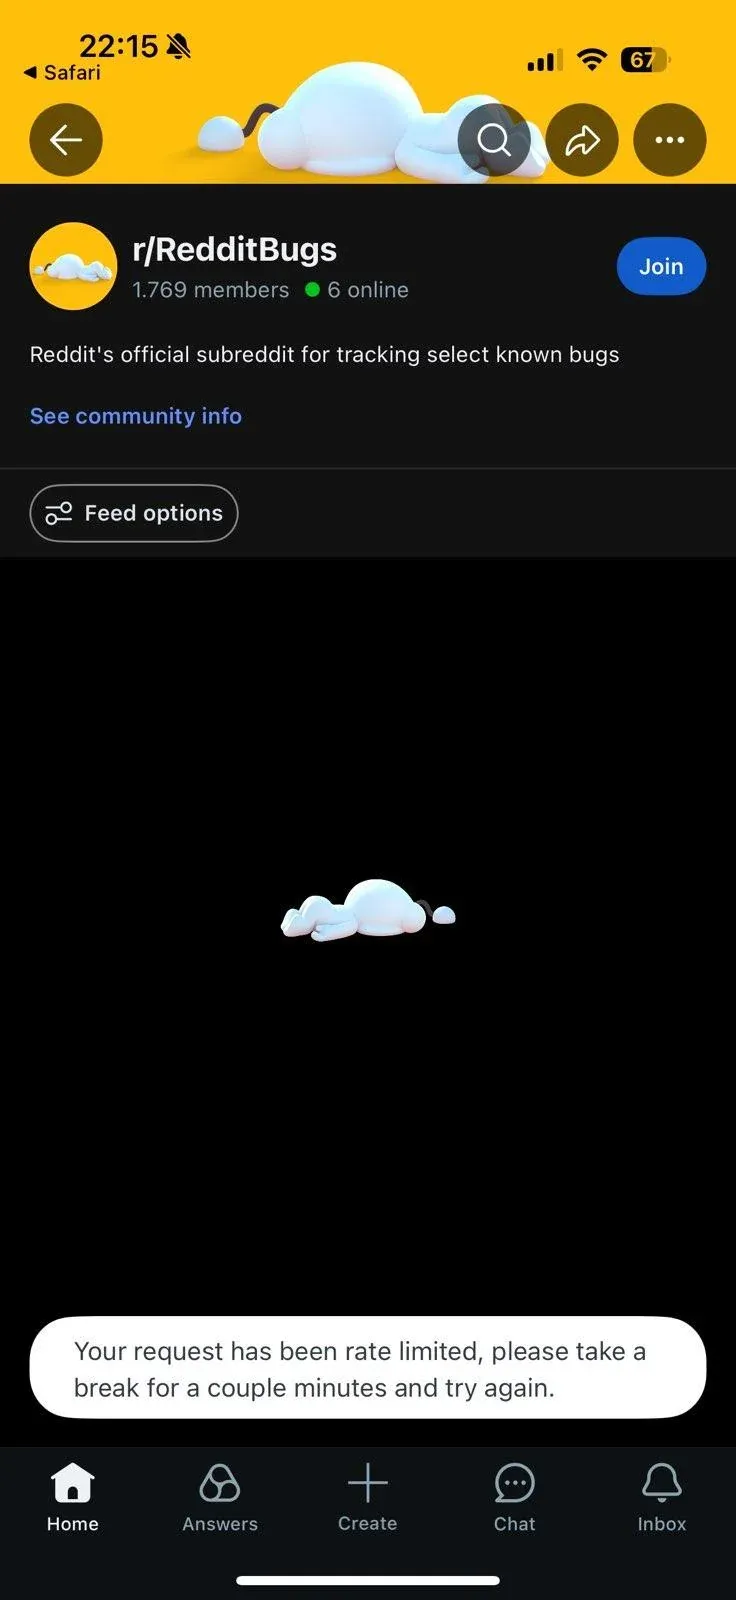
What Does “Rate Limit Exceeded” on Reddit Mean?
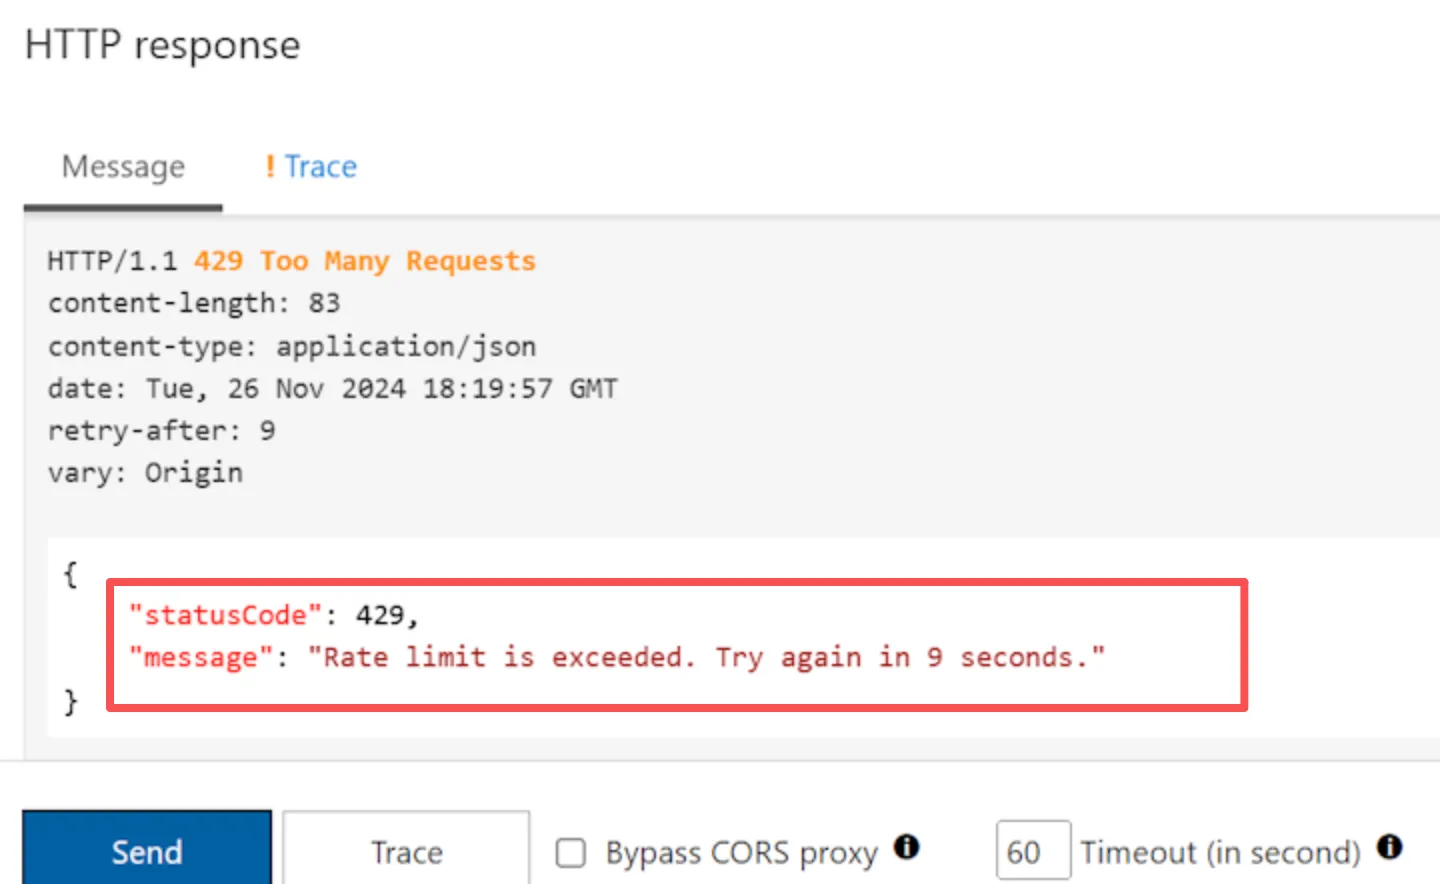
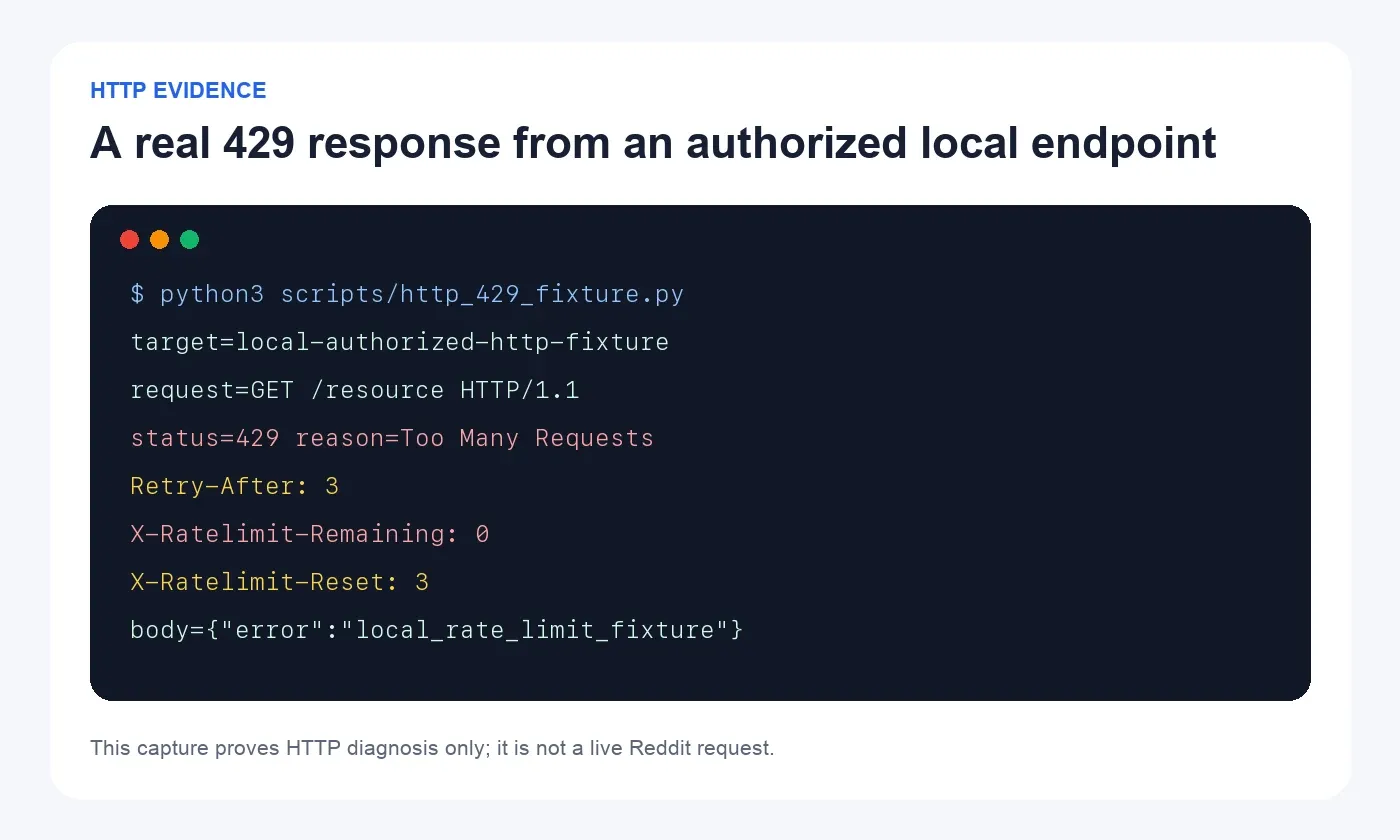
HTTP 429 means the server received the request but declined to process it because a rate limit was reached. The response may include Retry-After, which tells a client how long to wait. Our broader 429 Too Many Requests guide explains the status across services; this article focuses on Reddit’s interfaces and policies.
The status code does not reveal the counter by itself. Reddit may be limiting:
| Counter scope | Typical context | Evidence to inspect | Correct first response |
|---|---|---|---|
| Account | Posting, commenting, messaging, login | On-screen countdown, account notice, action type | Stop the action and wait |
| Browser or session | Repeated refreshes, extensions, duplicate tabs | Private-window comparison, background requests | Stop auto-refresh and isolate the client |
| OAuth client | Data API application | Rate-limit headers, application logs | Pause the shared queue and wait for reset |
| Source IP | Shared network or egress route | Same failure across clients on one route | Stop traffic and compare only through approved tests |
| Endpoint or action | One protected route | Error body, endpoint-specific documentation | Reduce that operation and follow its policy |
| Concurrency or burst | Parallel workers | In-flight count, timestamps, retry volume | Lower concurrency and centralize retries |
This is why a Reddit 429 is not proof of an IP ban. It is also not proof that an account was suspended. If the message reports a network-security restriction, treat it as a separate access problem instead of assuming every failure is a rate limit.
Why Does Reddit Apply Rate Limits?
Rate limits protect service capacity and help control spam, abusive automation, repeated login attempts, and excessive data collection. Reddit also uses access policies, robots guidance, authentication requirements, and other technical measures. In 2024, Reddit said it would continue rate limiting or blocking unknown bots and crawlers. In 2026, it announced that public API access would remain limited while new third-party applications increasingly move toward Reddit’s Developer Platform.
That policy context matters for anyone searching for a “Reddit scraper rate limit workaround.” The durable fix is workload control and approved access, not a faster evasion loop. Reddit’s current User Agreement says scraping without prior written consent is prohibited, apart from conditionally permitted crawling under robots.txt or access governed by a separate agreement. Commercial use and research above Data API limits may require a separate Reddit agreement.
Fix Reddit Rate Limit Exceeded in a Browser or App
If the warning appears during normal browsing, posting, commenting, messaging, or login, use this recovery sequence:
- Stop refreshing or resubmitting. Close duplicate Reddit tabs and pause extensions, scripts, or tools that reload pages in the background.
- Read the exact wording. Save the countdown, status code, affected action, and time. Do not include cookies or account tokens in a screenshot.
- Wait for the stated period. When the timer ends, make one test request. A burst of “just checking” requests can recreate the same condition.
- Separate interface from account. If ordinary use still fails, compare the official app and a supported browser without running automation. A private window can reveal a session issue, but it will not reset an account or IP counter.
- Check for a broader outage. If multiple unrelated devices and networks fail at the same time, consult Reddit’s status information before changing local settings.
- Use official recovery channels. A security lock, password problem, moderation action, or appeal notice needs its own official workflow. Do not treat it as a generic 429.
Clearing cookies is diagnostic, not a guaranteed fix. It signs you out and may reset a broken browser session, but it does not clear an OAuth quota, account cooldown, endpoint budget, or source-IP counter.
How Developers Should Handle a Reddit API 429
For an approved Data API application, capture a small, redacted evidence record before changing code:
- timestamp in UTC;
- HTTP method and endpoint path, without sensitive query data;
- status code and Reddit error code or safe body summary;
Retry-Afterand available rate-limit headers;- OAuth client identifier represented by a non-secret internal label;
- worker count, in-flight requests, attempt number, and elapsed time;
- cache hit or miss;
- a redacted request ID or trace ID.
Never log the OAuth token, client secret, cookies, proxy password, full authorization header, or a URL containing credentials.
1. Stop nested retry loops
HTTP libraries, job workers, orchestration tools, and application code can each have their own retry policy. When all four retry the same 429, a single failed request becomes a burst. Give one layer ownership of the retry budget and disable or narrow the others.
2. Treat the OAuth budget as shared state
Do not let every worker assume it owns the full allowance. Feed remaining and reset values into one shared scheduler. When the remaining budget approaches zero, stop admitting nonessential work. Reserve capacity for interactive or time-sensitive operations if your approved use case needs it.
3. Cache and deduplicate permitted reads
Store reusable responses for an appropriate period when Reddit’s rules and your data obligations allow it. Use a single-flight pattern so ten workers asking for the same resource create one outbound request. Retention must still respect deletions, removals, privacy requirements, and your approved use case.
4. Lower concurrency before lowering sleep intervals
A scraper can stay below an average requests-per-minute figure and still violate a burst or concurrency rule. Start with one worker, observe the headers, then increase carefully. A random delay attached to fifty simultaneous workers is still fifty workers.
5. Recheck current Reddit guidance
As of September 30, 2026, Reddit’s Data API Wiki lists 100 queries per minute per OAuth client ID for eligible free access, averaged over a ten-minute window. It also says traffic without OAuth or login credentials is not accepted. Treat that as current guidance, not a permanent contract: Reddit can change access, limits, and platform requirements.
Python Template for Bounded Reddit 429 Handling
The following template is for an approved OAuth workflow. It reads secrets from environment variables, validates the HTTPS host and allowed path before attaching a Bearer token, refuses redirects, and does not print credentials. Set AUTHORIZED_REDDIT_PATH_PREFIX to the narrowest approved path and REQUIRED_JSON_FIELDS to the comma-separated top-level fields required by that endpoint. Confirm the current endpoint, scopes, and access terms for your application before using it.
from datetime import datetime, timezone
from email.utils import parsedate_to_datetime
import math
import os
import random
import time
from typing import Optional
from urllib.parse import urlparse

import requests


OAUTH_TOKEN = os.environ["REDDIT_OAUTH_TOKEN"]
USER_AGENT = os.environ["REDDIT_USER_AGENT"]
AUTHORIZED_PATH_PREFIX = os.environ["AUTHORIZED_REDDIT_PATH_PREFIX"].rstrip("/") or "/"
REQUIRED_JSON_FIELDS = tuple(
    field.strip()
    for field in os.environ["REQUIRED_JSON_FIELDS"].split(",")
    if field.strip()
)

MAX_ATTEMPTS = 3
MAX_INLINE_WAIT_SECONDS = 300
TOTAL_ELAPSED_BUDGET_SECONDS = 360
ALLOWED_REDDIT_HOST = "oauth.reddit.com"


def validate_authorized_url(value: str) -> str:
    parsed = urlparse(value)
    prefix_matches = (
        parsed.path.startswith("/")
        if AUTHORIZED_PATH_PREFIX == "/"
        else parsed.path == AUTHORIZED_PATH_PREFIX
        or parsed.path.startswith(f"{AUTHORIZED_PATH_PREFIX}/")
    )
    if (
        parsed.scheme != "https"
        or parsed.hostname != ALLOWED_REDDIT_HOST
        or parsed.port not in (None, 443)
        or parsed.username is not None
        or parsed.password is not None
        or parsed.fragment
        or not prefix_matches
    ):
        raise ValueError("Refusing a Reddit URL outside the approved HTTPS host and path")
    return value


if not REQUIRED_JSON_FIELDS:
    raise ValueError("REQUIRED_JSON_FIELDS must name the endpoint's required fields")

AUTHORIZED_URL = validate_authorized_url(os.environ["AUTHORIZED_REDDIT_URL"])


def parse_retry_after(value: Optional[str]) -> Optional[int]:
    if value is None:
        return None
    text = value.strip()
    if text.isdigit():
        return int(text)
    try:
        retry_at = parsedate_to_datetime(text)
    except (TypeError, ValueError, OverflowError):
        return None
    if retry_at.tzinfo is None:
        return None
    seconds = (retry_at - datetime.now(timezone.utc)).total_seconds()
    return max(0, math.ceil(seconds))


def parse_reset_seconds(value: Optional[str]) -> Optional[int]:
    if value is None:
        return None
    try:
        seconds = float(value.strip())
    except (TypeError, ValueError):
        return None
    if not math.isfinite(seconds) or seconds < 0:
        return None
    return math.ceil(seconds)


def parse_wait_seconds(response: requests.Response) -> int:
    candidates = [
        parse_retry_after(response.headers.get("Retry-After")),
        parse_reset_seconds(response.headers.get("X-Ratelimit-Reset")),
    ]
    valid = [value for value in candidates if value is not None]
    if not valid:
        raise RuntimeError("429 had no valid Retry-After or reset value; defer the job")
    return max(1, max(valid))


def validate_success_payload(response: requests.Response) -> dict:
    media_type = response.headers.get("Content-Type", "").split(";", 1)[0].lower()
    if media_type != "application/json" and not media_type.endswith("+json"):
        raise RuntimeError(f"Unexpected success content type: {media_type or 'missing'}")
    try:
        payload = response.json()
    except ValueError as exc:
        raise RuntimeError("Success response did not contain valid JSON") from exc
    if not isinstance(payload, dict):
        raise RuntimeError("Success JSON did not match the expected object shape")
    missing = [field for field in REQUIRED_JSON_FIELDS if field not in payload]
    if missing:
        raise RuntimeError(f"Success JSON is missing required fields: {', '.join(missing)}")
    return payload


session = requests.Session()
session.headers.update(
    {
        "Authorization": f"Bearer {OAUTH_TOKEN}",
        "User-Agent": USER_AGENT,
        "Accept": "application/json",
    }
)

started_at = time.monotonic()

for attempt in range(1, MAX_ATTEMPTS + 1):
    elapsed = time.monotonic() - started_at
    if elapsed >= TOTAL_ELAPSED_BUDGET_SECONDS:
        raise RuntimeError("Elapsed-time budget exhausted before the next request")

    try:
        response = session.get(
            AUTHORIZED_URL,
            timeout=(5, 20),
            allow_redirects=False,
        )
    except requests.Timeout as exc:
        raise RuntimeError("Reddit request timed out; no retry was scheduled") from exc
    except requests.RequestException as exc:
        raise RuntimeError("Reddit request failed before a valid response arrived") from exc

    if 300 <= response.status_code < 400:
        raise RuntimeError("Redirect refused so the Bearer token stays on the approved host")

    if response.status_code == 429:
        wait_seconds = parse_wait_seconds(response)
        if attempt == MAX_ATTEMPTS:
            raise RuntimeError("Reddit rate limit persisted after bounded attempts")
        if wait_seconds > MAX_INLINE_WAIT_SECONDS:
            raise RuntimeError(
                f"Defer this job for at least {wait_seconds} seconds instead of sleeping inline"
            )

        sleep_seconds = wait_seconds + random.uniform(0.25, 1.0)
        if time.monotonic() - started_at + sleep_seconds > TOTAL_ELAPSED_BUDGET_SECONDS:
            raise RuntimeError("Defer the job because the next wait exceeds its elapsed-time budget")
        time.sleep(sleep_seconds)
        continue

    if not 200 <= response.status_code < 300:
        try:
            response.raise_for_status()
        except requests.HTTPError as exc:
            raise RuntimeError(f"Reddit returned HTTP {response.status_code}") from exc
        raise RuntimeError(f"Unexpected non-success HTTP status: {response.status_code}")

    validate_success_payload(response)
    print(
        "Validated Reddit JSON response",
        response.status_code,
        "required_fields=",
        ",".join(REQUIRED_JSON_FIELDS),
    )
    break
else:
    raise RuntimeError("Request loop ended without a response")
This pattern is deliberately conservative. An HTTP-date Retry-After and a decimal X-Ratelimit-Reset are both accepted; when both are valid, the longer wait wins. Invalid wait headers stop the job instead of being guessed. The (5, 20) timeout limits the connection and response-read phases of one request; it is not, by itself, a whole-job deadline. The separate elapsed-time budget is checked before another request or sleep. The template also rejects redirects, classifies connection failures, and verifies JSON plus endpoint-required fields before reporting success. It does not switch client IDs, create new accounts, spoof a browser user agent, or route around the quota. For deeper retry design, including which methods are safe to repeat, see the Python Requests retry guide.
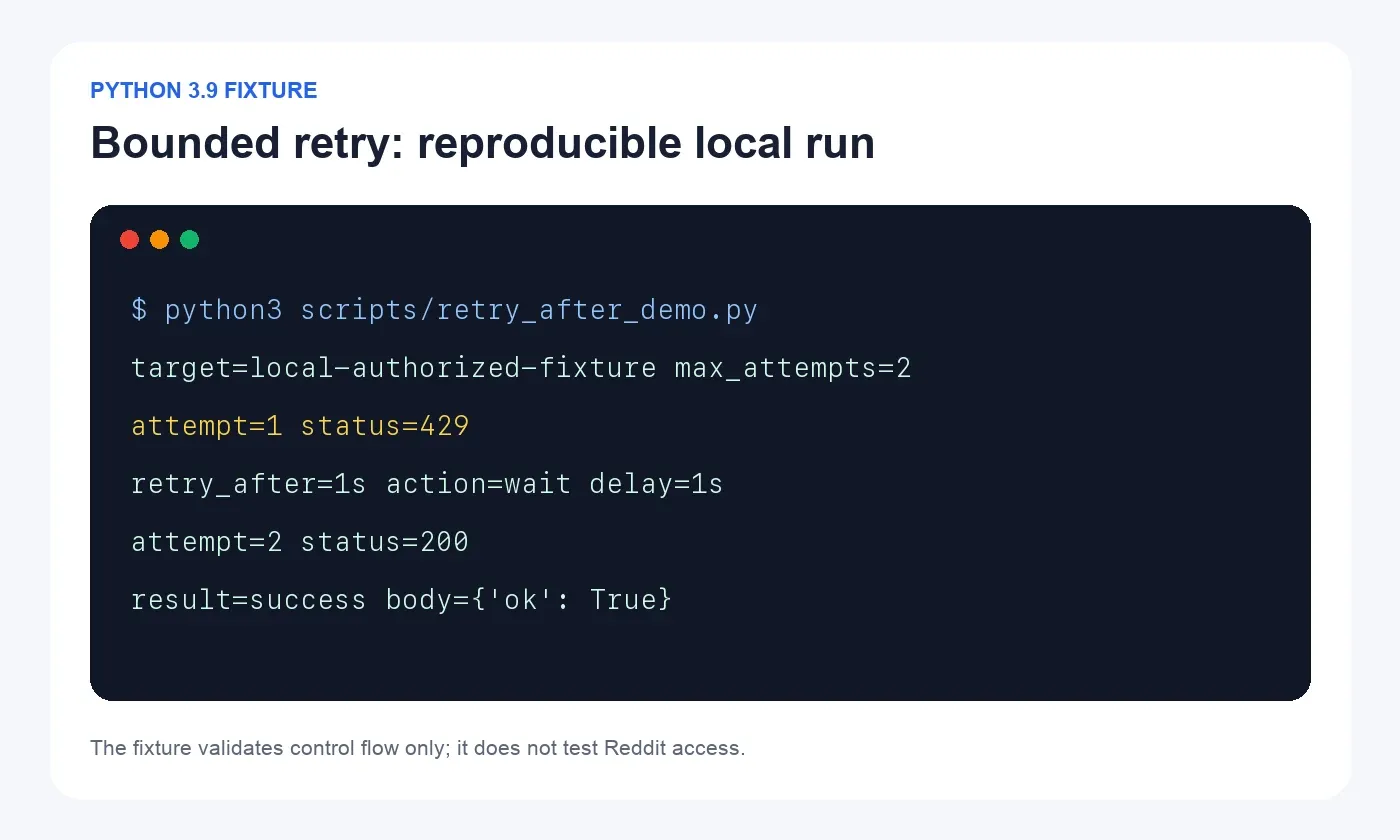
The bounded control flow was also exercised against a deterministic local fixture that returned one 429 with Retry-After: 1, followed by a 200 response. That run verifies the wait and attempt logic only. It does not claim live Reddit API access or confirm credentials.
Can You Bypass a Reddit Rate Limit With a Rotating Proxy?
Do not use proxy rotation to circumvent a Reddit account, OAuth client, or published API limit. A proxy changes the network egress address. It does not change the OAuth client ID, expand an application budget, clear an account cooldown, repair a broken session, or grant permission to collect Reddit data.
This distinction answers the keyword “how to bypass rate limit Reddit” more accurately: first identify the counter, then use Reddit’s approved capacity or recovery path. If the counter is tied to an OAuth client, rotating IPs leaves the actual quota unchanged. If the limit protects login or posting, cycling exits can make the activity look less consistent and can conflict with platform rules.
When a proxy may be relevant
A proxy can be appropriate when the project already has authorization and needs controlled network routing for a separate reason, such as regional advertising QA, comparing public experiences across approved markets, or isolating test routes. Even then:
- keep Reddit’s total permitted request rate in place;
- use the correct OAuth identity and a descriptive user agent;
- preserve session continuity when the workflow depends on cookies;
- record the country, route label, session mode, and result;
- stop on 401, 403, 429, login walls, or unclear authorization.
Choose the route and session mode from the workflow’s state requirements, not from a desire to increase request volume:
| Request source | Appropriate session choice | Validation evidence |
|---|---|---|
| Python Requests | Keep one stable route for a bounded authenticated job; rotate only between independent, authorized regional tests | Compare a direct-control run and a proxy run with the same OAuth client, endpoint, concurrency, and schedule; validate status, JSON fields, and recorded country |
| Scrapy | Keep throttling, concurrency, and retry ownership centralized; use separate named sessions only for independent market batches | Check duplicate rates, item counts, required fields, 401/403/429 responses, and the route label for each batch |
| Selenium | Use a sticky session for login, cookies, redirects, and other multi-step journeys; do not rotate per request inside the journey | Record the target country, start and end exit, session mode, final URL, and expected page element without storing cookies or proxy credentials |
Rola IP’s Reddit proxy solution separates stable campaign journeys from distributed public-research jobs. Its current proxy-network guide documents rotating residential, rotating datacenter, and mobile networks, plus sessionid, sessiontime, and per-request rotation controls. For the use cases in this article, rotating residential is relevant only when an authorized job needs residential routing or regional comparison. Use a sticky residential session when cookies, login state, pagination, or a repeatable browser journey must keep one exit; rotate between independent jobs or countries only when each job is stateless. Per-request rotation is a poor fit for Selenium and other stateful flows because the IP can change while the cookie session remains the same.
Before scaling, run a one-variable comparison: keep the Reddit identity, request rate, payload, client version, and time window fixed; change only the approved route. Confirm the configured egress and country with a safe IP-check endpoint, then validate the Reddit response or browser result against explicit required fields or page elements. Record the route label and session mode, not the proxy password. If the control and routed runs fail with the same OAuth 429, the evidence does not support an IP-routing diagnosis. None of these choices expands Reddit’s Data API allowance or defeats an enforcement action.
A Better Reddit Scraper Rate Limit Workaround
For a compliant data pipeline, “workaround” should mean reducing unnecessary demand and moving to an approved access model. The web scraping versus API guide can help teams choose the correct interface before scaling a collector. Use this order:
- Confirm that Reddit permits the use case, data fields, retention period, and access method.
- Use OAuth or the applicable Developer Platform capability. Identify the application accurately.
- Put all outbound requests behind one queue with an explicit concurrency ceiling.
- Track remaining budget and reset time as shared application state.
- Cache permitted responses and deduplicate identical work.
- Use incremental collection instead of repeatedly downloading the same history.
- Stop the job when permission, authentication, or response integrity becomes unclear.
- Request approved commercial or higher-volume access when the business need exceeds the available limit.
Also validate the content, not just the status code. A 200 OK response can still contain a login page, consent screen, error shell, or incomplete data. Check the final URL, content type, required fields, pagination state, and record count before marking a job successful.
Prevention Checklist
Before the next scheduled run, verify that:
- one component owns retries;
- the attempt count and total elapsed time are bounded;
- workers share rate-limit state;
- duplicate reads are coalesced;
- secrets are excluded from logs;
- 401, 403, 429, redirects, and unexpected 200 pages are classified separately;
- current Reddit terms and developer guidance have been reviewed;
- the data retention and deletion process matches the approved use case;
- any proxy route serves a documented regional or network requirement, not quota evasion.
The practical lesson is simple: a Reddit rate limit exceeded error is a scheduling and access signal, not an invitation to hide the requesting identity. Capture the signal, match the fix to the counter, and keep the workload inside Reddit’s permitted route.
Disclosure: This article is published by Rola IP. Product examples should be evaluated against current Rola IP documentation, Reddit’s current rules, and the reader’s authorized use case.
Conclusion
Resolving Reddit rate limit exceeded starts with identifying the affected access path, not changing IP addresses. Pause new requests, inspect the available retry and reset headers, coordinate the budget across workers, and validate the returned data before resuming an authorized workflow. If demand exceeds the permitted capacity, seek approved access rather than multiplying retries or switching identities.
For projects with a separate, authorized regional or network-routing requirement, Rola IP’s residential proxies can be evaluated according to the required location and session continuity. Keep stateful journeys on a consistent route where needed, and reserve rotation for independent tests that permit it. Verify current product capabilities before deployment: proxy routing does not expand an OAuth quota, clear an account cooldown, or grant permission to collect Reddit data.