Web Scraping Reddit Posts, Comments, and Replies with Python
Sep 29, 2026 · Guides · 15 min read
If you want to analyze popular discussions in a subreddit, find posts by keyword, or organize the comments and nested replies in a discussion, the first step is to determine which access method you are allowed to use. This guide walks through data fields, connecting with PRAW, post listings, search, single-post retrieval, comment trees, and CSV exports, while also explaining the appropriate boundaries for public-page parsing and proxy integration.
TL;DR
Use an approved Reddit API application with PRAW for structured collection. Keep post and parent IDs to reconstruct replies, record UTC timestamps, and verify CSV content before analysis. Expanding comments adds requests; a row limit does not limit expansion costs. A proxy changes network egress but cannot grant API permission or raise your quota.
Validation scope: The complete script below passed offline checks on Windows with Python 3.12.10 on September 28, 2026, using the dependency versions shown below. Live Reddit API and proxy connectivity remain unverified for this version.
What Data Can Reddit Scraping Collect?
| Object | Common fields | Typical use cases |
|---|---|---|
| Subreddit | Name, description, member count, and public attributes | Define the discussion scope and understand community context |
| Posts | Title, body, author, publication time, score, comment count, URL | Topic research, content trends, and issue categorization |
| Comments and replies | Body, author, time, score, post_id, parent_id |
Feedback analysis, conversation relationships, and recurring questions |
| Public user activity | Public submissions or comments and their links | Analyze public content only within the approved scope; minimize personal data |
Comment counts and scores can change, and deleted or removed content may no longer be available. Each exported row should ideally retain the original link, collection time, and community name so the source can be verified later. Do not assume that the comment count displayed on a post page will always equal the number of rows you export.
The complete exporter below omits author names by default; enable them only if necessary for your approved purpose. Define a retention period and a process for applicable deletion requests before collecting content.
How to Scrape Reddit?
| Method | Best suited for | Key considerations |
|---|---|---|
| Data API + PRAW | You have approved OAuth credentials and need stable fields and batch exports | Run within official rate limits; PRAW handles objects and pagination |
| HTML + BeautifulSoup | You are permitted to read a small number of public pages and need to verify visible information | Validate the actual content and selectors; page structure can change easily |
| No-code templates | You already know a small number of post URLs and want Excel or CSV output | Check which URLs, reply depths, and export fields the template supports |
For long-term, repeatable collection, prioritize an official interface with stable fields and traceable errors. If you only need to inspect visible information on a few pages, an authorized HTML-reading approach may be sufficient. In either case, verify that the response contains post content rather than a login or challenge page that happens to return HTTP 200.
For a broader comparison of official APIs and page-level web scraping, see Rola-IP’s web scraping versus an API guide. The Reddit API workflow below is the preferred example when you need structured posts, comments, and reply relationships.
Before running anything, review the Reddit Data API Terms, your approved use case, and any data-retention requirements. PRAW is an API client; it does not automatically obtain permission for your application.
Python Reddit Scraper: Install PRAW and Verify Credentials
- Install Python 3.10 or later, then install PRAW.
- Follow Reddit’s current process to apply for credentials suitable for an external script. Prepare a client ID, client secret, and a distinctive user agent.
- Supply secrets through environment variables or a secret manager. The values below are placeholders, not instructions to type live credentials into saved shell history.
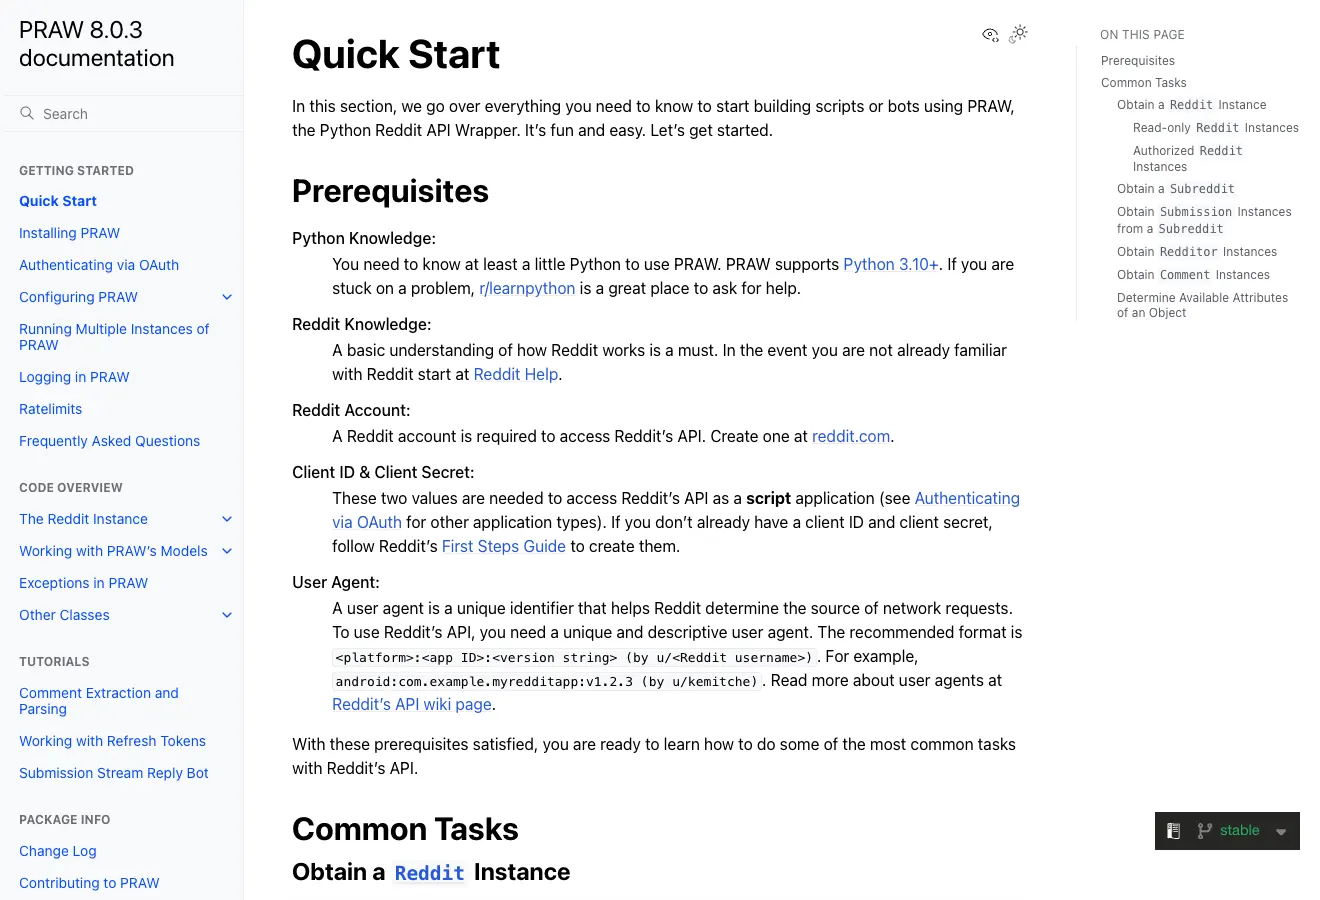
Figure 1. PRAW Quick Start documentation explaining credentials.
The current syntax for credential fields and a read-only instance is shown in the PRAW Quick Start. The following commands are for macOS or Linux; in PowerShell, use $env:REDDIT_CLIENT_ID="your_client_id" and the same syntax for REDDIT_CLIENT_SECRET and REDDIT_USER_AGENT. These are placeholders; supply real secrets securely instead of typing them into saved command history.
Code 1. Installation and environment variables
python -m pip install beautifulsoup4==4.15.0 certifi==2026.7.22 charset-normalizer==3.5.1 defusedxml==0.7.1 idna==3.20 praw==8.0.3 prawcore==4.0.0 requests==2.34.2 soupsieve==2.10 typing_extensions==4.16.0 update_checker==1.0.0 urllib3==2.8.0 websocket-client==1.9.2
export REDDIT_CLIENT_ID="your_client_id"
export REDDIT_CLIENT_SECRET="your_client_secret"
export REDDIT_USER_AGENT="macos:research-export:1.0 (by u/your_name)"
Code 2. Verify API access by retrieving one post
import os
import praw

reddit = praw.Reddit(
    client_id=os.environ["REDDIT_CLIENT_ID"],
    client_secret=os.environ["REDDIT_CLIENT_SECRET"],
    user_agent=os.environ["REDDIT_USER_AGENT"],
    timeout=20,
    ratelimit_seconds=0,
    check_for_updates=False,
)
try:
    posts = list(reddit.subreddit("Python").new(limit=1))
    if posts:
        print("API returned post:", posts[0].id)
    else:
        print("Listing returned no posts; inspect scope and community.")
except Exception as exc:
    # Avoid printing raw exception URLs or credentials.
    print("API check failed:", type(exc).__name__)
    raise SystemExit(1)
Printing a subreddit name alone does not establish API connectivity: PRAW can store that name without fetching data. This example consumes a listing and reports a returned post ID; an empty result is not an authentication failure. For 401 or 403 errors, first check the application status, credentials, and approved scope.
Scrape Reddit Data: Get Subreddit Posts and Automatic Pagination
- Choose the community name and sort order.
newis useful for the latest discussions,hotfor current popularity, andtopcan be combined with time windows such asweekormonth. - Set
limitto control how many items are retrieved. PRAW’s listing generator continues requests using cursors returned by the API, so your code does not need to manually construct webpage pagination URLs. A largelimitstill has to comply with your approved quota. - Save fields that let you trace the source later.
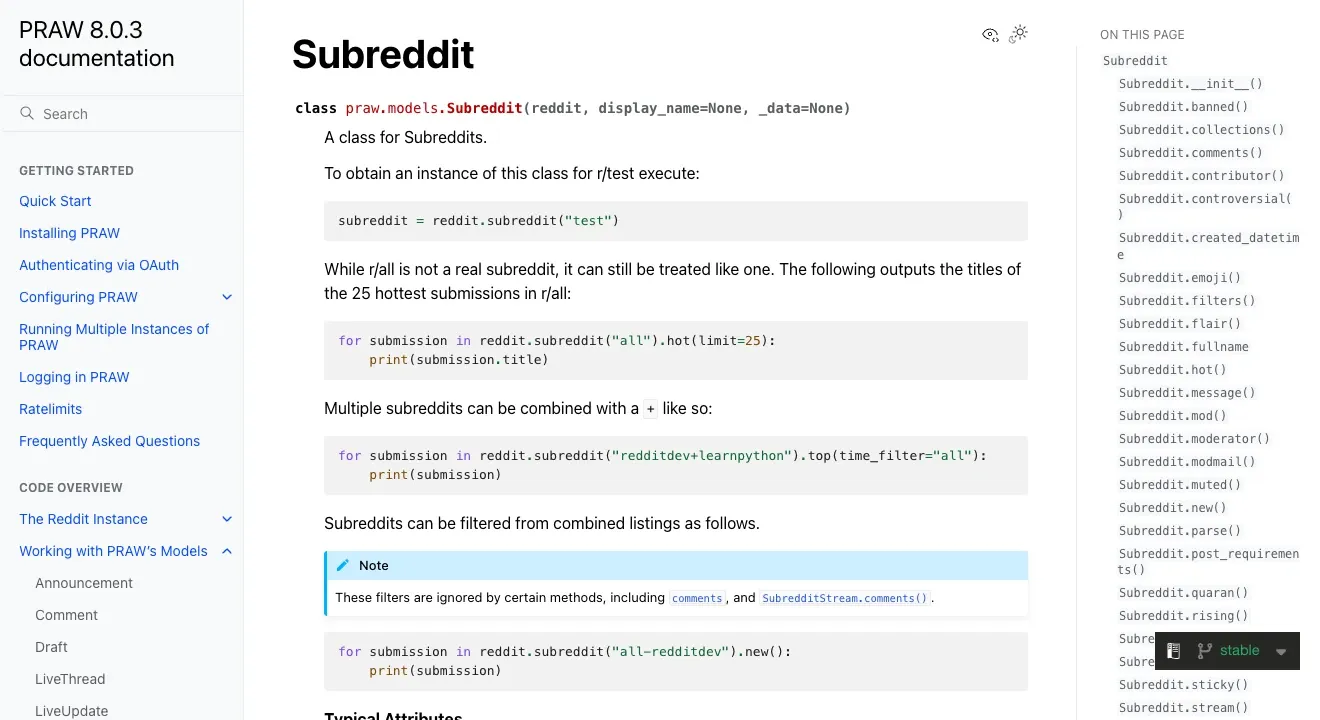
Figure 2. PRAW Subreddit documentation showing the official entry points for listings and search.
Code 3. Latest posts and this week’s top-scoring posts
subreddit = reddit.subreddit("Python")
for post in subreddit.new(limit=10):
    print(post.id, post.title, post.score, post.num_comments)

for post in subreddit.top(time_filter="week", limit=10):
    print(post.id, post.title)
If you only need posts, you do not have to expand comments. A post title, body, and media URL are separate fields: a text post may have content in selftext, a link post may have an empty selftext, and post.url points to the submitted target. Save both so an empty body is not mistaken for an empty post later.
Code 4. Extract the core fields from one post
from datetime import datetime, timezone

row = {
    "post_id": post.id,
    "title": post.title,
    "body": post.selftext or "",
    "url": post.url,
    "permalink": "https://www.reddit.com" + post.permalink,
    "created_at_utc": datetime.fromtimestamp(post.created_utc, timezone.utc).isoformat(),
}
Reddit Scraping: Search Posts by Keyword
- Restrict the query to the target subreddit so a broad search does not introduce unnecessary irrelevant results.
- Choose the search term, sort order, and time range.
- Manually inspect the first few results before increasing the volume. Search results are not a complete historical archive of the topic.
Code 5. Search for posts from the past month containing a specified topic
results = reddit.subreddit("Python").search(
    "proxy", sort="new", time_filter="month", limit=20)
for post in results:
    print(post.id, post.title, post.permalink)
The query term proxy is only an example. In practice, use terms that match your research question. Search results can be affected by platform indexing, permissions, and deletion status. If you need to compare multiple communities, save the same filter conditions for each one.
How to Scrape Reddit: Single-Post Content and Public Community Information
Once you have a post ID, you can request the submission object directly. This is better for checking a specific discussion than locating it again through a listing. The ID is the identifier after /comments/, not the full URL. When community context is needed, separately read public subreddit attributes such as the description; some fields may be empty in certain communities.
Code 6. Single post and public community information
post = reddit.submission(id="replace_with_post_id")
print(post.title)
print(post.selftext)
print(post.url)
print(post.score, post.num_comments)

community = reddit.subreddit("Python")
print(community.display_name, community.public_description)
Reddit Comment Scraper: Scrape Comments and Nested Replies
- Load the target submission.
- Start with a finite expansion budget such as
replace_more(limit=2), then flatten the remaining comment tree. Uselimit=0to remove placeholders without expanding them. - Save
post_id,comment_id, andparent_idfor each comment. A top-level comment commonly has at3_post ID as its parent, while a reply commonly has at1_comment ID as its parent. These fields let you rebuild the nested reply structure.
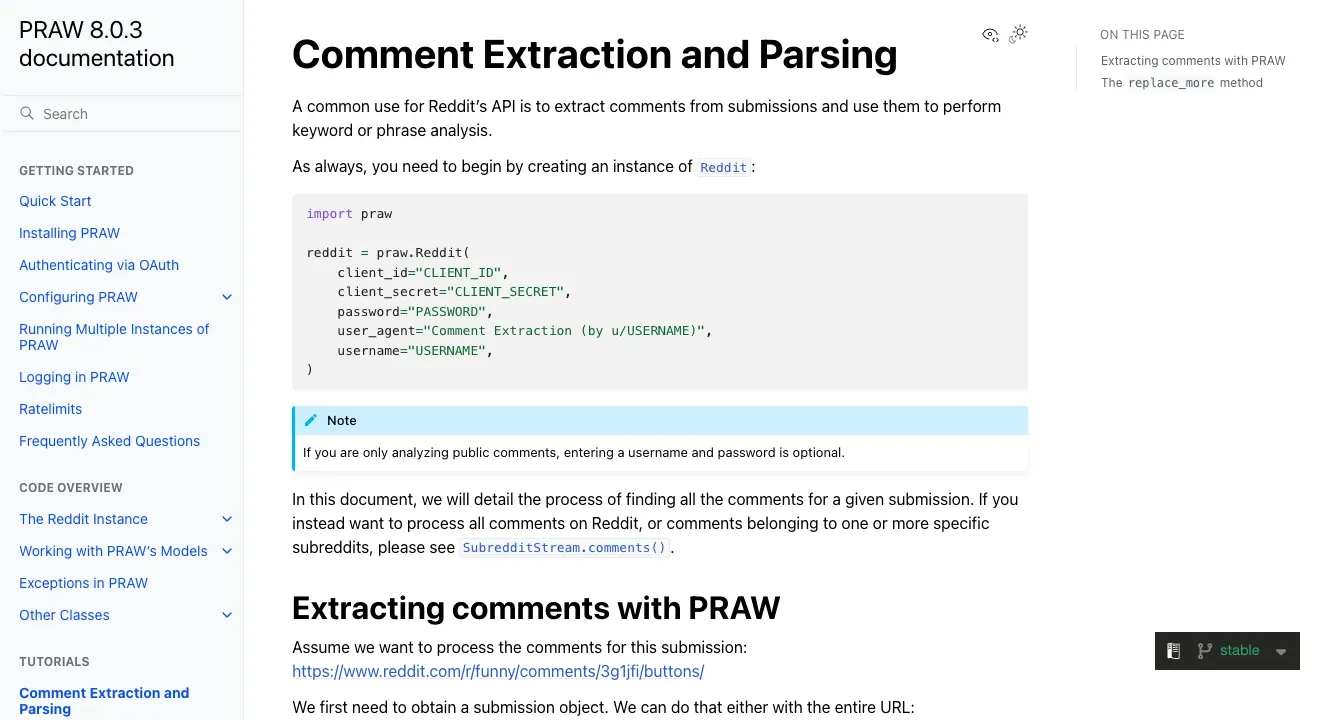
Figure 3. PRAW comment extraction documentation introducing client configuration and submission retrieval.
Code 7. Expand the comment tree and preserve reply relationships
post = reddit.submission(id="replace_with_post_id")
post.comments.replace_more(limit=2)
for comment in post.comments.list()[:50]:
    print({
        "post_id": post.id,
        "comment_id": comment.id,
        "parent_id": comment.parent_id,
        "body": comment.body,
        "permalink": "https://www.reddit.com" + comment.permalink,
    })
replace_more(limit=None) attempts to expand placeholder nodes as fully as possible, which creates additional requests; large popular threads can therefore be slow. If you only want the first batch of already loaded comments, use replace_more(limit=0), but the data will be incomplete. Applying [:50] only limits the final number of exported comments; it does not reduce the earlier cost of expanding the full comment tree. Omit author names unless needed, and do not try to recover removed content. Truncated exports can omit a reply’s parent; a preserved parent_id does not guarantee that the parent row is present.
For more detail on comment trees, see PRAW Comment Extraction and Parsing.
Python Reddit Scraper: Export Posts and Comments to CSV
It is easier to analyze posts and comments when they are split into two files: reddit_posts.csv, with one row per post, and reddit_comments.csv, with one row per comment. post_id is the join key between the two tables, while parent_id preserves the reply hierarchy. Earlier examples illustrate individual operations. Copy the complete script below into a new UTF-8 file named reddit_scraper_v2.py. It contains all imports, configuration, CSV export, and failure handling; no code attachment is required.
Code 8. Complete exporter: save as reddit_scraper_v2.py
"""Small authorized Reddit exports. No credentials or raw exception URLs are logged."""
import argparse
import csv
import json
import logging
import os
import sys
import time
from datetime import datetime, timezone
from pathlib import Path

import praw
import requests

POST_FIELDS = ["subreddit", "post_id", "title", "body", "author", "created_at_utc",
               "collected_at_utc", "score", "num_comments", "url", "permalink"]
COMMENT_FIELDS = ["subreddit", "post_id", "comment_id", "parent_id", "body",
                  "author", "created_at_utc", "collected_at_utc", "score", "permalink"]


def utc(seconds=None):
    return datetime.fromtimestamp(seconds if seconds is not None else time.time(),
                                  timezone.utc).isoformat()


def post_row(post, include_authors=False):
    return dict(subreddit=post.subreddit.display_name, post_id=post.id,
                title=post.title, body=post.selftext or "",
                author=str(post.author) if include_authors and post.author else "",
                created_at_utc=utc(post.created_utc), collected_at_utc=utc(),
                score=post.score, num_comments=post.num_comments, url=post.url,
                permalink="https://www.reddit.com" + post.permalink)


def comment_row(comment, post, include_authors=False):
    return dict(subreddit=post.subreddit.display_name, post_id=post.id,
                comment_id=comment.id, parent_id=comment.parent_id, body=comment.body,
                author=str(comment.author) if include_authors and comment.author else "",
                created_at_utc=utc(comment.created_utc), collected_at_utc=utc(),
                score=comment.score, permalink="https://www.reddit.com" + comment.permalink)


def safe_cell(value):
    # Protect spreadsheet users from untrusted formula-like text.
    if isinstance(value, str) and value.lstrip().startswith(("=", "+", "-", "@")):
        return "'" + value
    return value


def write_csv(path, fields, rows):
    with path.open("w", encoding="utf-8-sig", newline="") as handle:
        writer = csv.DictWriter(handle, fieldnames=fields)
        writer.writeheader()
        writer.writerows({key: safe_cell(value) for key, value in row.items()} for row in rows)


def make_client():
    # Library retry messages may include request details; emit only our sanitized errors.
    logging.getLogger("prawcore").disabled = True
    logging.getLogger("praw").disabled = True
    names = ["REDDIT_CLIENT_ID", "REDDIT_CLIENT_SECRET", "REDDIT_USER_AGENT"]
    if any(not os.environ.get(name) for name in names):
        raise ValueError("Set REDDIT_CLIENT_ID, REDDIT_CLIENT_SECRET and REDDIT_USER_AGENT.")
    session = requests.Session()
    session.trust_env = False  # Explicit proxy configuration; no accidental inherited route.
    proxy = os.environ.get("ROLA_PROXY_URL")
    if proxy:
        if not proxy.startswith(("http://", "https://")):
            raise ValueError("ROLA_PROXY_URL must be an HTTP(S) proxy URL.")
        session.proxies.update(http=proxy, https=proxy)
    return praw.Reddit(client_id=os.environ[names[0]], client_secret=os.environ[names[1]],
                       user_agent=os.environ[names[2]], requestor_kwargs={"session": session},
                       timeout=20, ratelimit_seconds=0, check_for_updates=False)


def export(reddit, args):
    # Refuse to overwrite an existing export, including one from a failed attempt.
    folder = Path(args.output_dir)
    folder.mkdir(parents=True, exist_ok=False)
    posts, comments = [], []
    start = time.monotonic()
    state = {"status": "running", "started_at_utc": utc(),
             "mode": "single" if args.post_id else "search" if args.query else "new",
             "post_limit": args.limit, "comments_per_post": args.comments_per_post,
             "more_limit": args.more_limit, "include_authors": args.include_authors,
             "proxy_enabled": bool(os.environ.get("ROLA_PROXY_URL")),
             "coverage": "bounded sample; not a complete archive"}
    failure = None
    try:
        if args.post_id:
            source = [reddit.submission(id=args.post_id)]
        elif args.query:
            source = reddit.subreddit(args.subreddit).search(
                args.query, sort="new", time_filter="month", limit=args.limit)
        else:
            source = reddit.subreddit(args.subreddit).new(limit=args.limit)
        for post in source:
            if time.monotonic() - start >= args.max_seconds:
                state["status"] = "stopped_at_time_budget"
                break
            posts.append(post_row(post, args.include_authors))  # Forces server attributes.
            if args.comments_per_post:
                post.comments.replace_more(limit=args.more_limit)
                for comment in post.comments.list()[:args.comments_per_post]:
                    comments.append(comment_row(comment, post, args.include_authors))
        else:
            state["status"] = "completed" if posts else "completed_empty"
    except Exception as exc:
        failure = exc
        state["status"] = "failed_partial"
        state["error_type"] = type(exc).__name__
        response = getattr(exc, "response", None)
        if response is not None:
            state["http_status"] = response.status_code
            state["retry_after"] = response.headers.get("Retry-After")
    finally:
        write_csv(folder / "reddit_posts.csv", POST_FIELDS, posts)
        write_csv(folder / "reddit_comments.csv", COMMENT_FIELDS, comments)
        state.update(finished_at_utc=utc(), posts=len(posts), comments=len(comments))
        (folder / "run_metadata.json").write_text(json.dumps(state, indent=2), encoding="utf-8")
    if failure:
        # Do not print exception messages that can contain credentials or URLs.
        print("Export stopped: " + type(failure).__name__ +
              ". Inspect run_metadata.json; partial files are not a successful run.", file=sys.stderr)
        return 1
    print(json.dumps(state, indent=2))
    return 0 if state["status"] in ("completed", "completed_empty") else 2


def parser():
    result = argparse.ArgumentParser(description=__doc__)
    mode = result.add_mutually_exclusive_group()
    mode.add_argument("--query")
    mode.add_argument("--post-id")
    result.add_argument("--subreddit", default="Python")
    result.add_argument("--limit", type=int, default=10)
    result.add_argument("--comments-per-post", type=int, default=50)
    result.add_argument("--more-limit", type=int, default=0)
    result.add_argument("--max-seconds", type=int, default=120)
    result.add_argument("--include-authors", action="store_true")
    result.add_argument("--output-dir", default="reddit_output")
    return result


def main():
    arg_parser = parser()
    args = arg_parser.parse_args()
    for name, low, high in [("limit", 1, 100), ("comments_per_post", 0, 500),
                            ("more_limit", 0, 10), ("max_seconds", 1, 600)]:
        if not low <= getattr(args, name) <= high:
            arg_parser.error(f"{name} must be between {low} and {high}")
    try:
        with make_client() as reddit:
            return export(reddit, args)
    except ValueError as exc:
        print(str(exc), file=sys.stderr)
    except FileExistsError:
        print("Output directory already exists. Choose a new --output-dir.", file=sys.stderr)
    except Exception as exc:
        print("Stopped: " + type(exc).__name__, file=sys.stderr)
    return 1


if __name__ == "__main__":
    raise SystemExit(main())
Run the exporter
Open a terminal in the folder where you saved the script. Use the Python environment and credentials configured above. Choose a new output directory for each run. Replace POST_ID with an actual permitted post ID, such as the ID returned by Code 2. The default community is Python; use --subreddit NAME to change it for listing or search.
Three run modes: post listing, keyword search, and single-post comments
python reddit_scraper_v2.py --limit 10 --comments-per-post 0 --output-dir reddit_posts_run
python reddit_scraper_v2.py --query proxy --limit 10 --more-limit 2 --output-dir reddit_search_run
python reddit_scraper_v2.py --post-id POST_ID --more-limit 2 --output-dir reddit_thread_run
After export, inspect up to five rows from each CSV, or all rows if fewer are available. The post_id values in the post and comment files should match; a reply’s parent_id should point to the post or the previous-level comment; created_at_utc should be an ISO 8601 UTC string with a +00:00 offset; and permalink should return to the original discussion. score and num_comments are only snapshots from the time of collection and may change later.
The script creates both CSV files and run_metadata.json in a new output directory; it refuses to overwrite an existing directory. Check the status and row counts before using the files. A failed run preserves partial rows with status failed_partial and exits unsuccessfully. completed_empty is an empty listing, not proof that the intended data was obtained.
Defaults are 10 posts, 50 exported comments per post and zero MoreComments expansions. --more-limit caps expansions per post, not total HTTP requests. --max-seconds checks elapsed time between posts; it is not a hard deadline and fetching the next listing page, an in-flight post, or a library wait can overrun it. Parent rows may be absent after truncation. Text that could be interpreted as a spreadsheet formula is prefixed with an apostrophe.
When HTML Parsing Works for Web Scraping Reddit
If your permissions allow you to read public pages and your task only requires fields visible on the page, you can install beautifulsoup4 and parse HTML. However, modern Reddit may return challenge pages, login pages, or dynamic components. HTTP 200 only tells you that the request received a response; it does not prove that you received the post content. Before parsing, verify that the expected target elements exist and keep tests that detect structural changes. The installation command above includes BeautifulSoup; for this HTML example alone, use python -m pip install beautifulsoup4==4.15.0.
Code 9. Parse only page HTML that you are permitted to obtain
"""Parse an already-permitted HTML response and fail on challenge/changed markup."""

from bs4 import BeautifulSoup


def parse_visible_posts(html):
    soup = BeautifulSoup(html, "html.parser")
    rows = []
    for tag in soup.select("shreddit-post"):
        title = tag.get("post-title")
        permalink = tag.get("permalink")
        if title and permalink:
            rows.append({"title": title, "permalink": permalink})
    if not rows:
        raise ValueError("No post elements; inspect page or challenge response")
    return rows
This selector comes from an example of a public-page structure and is not guaranteed to remain valid. If you need complete comments, parent-child relationships, or stable fields across many pages, prioritize the approved Data API workflow described above.
How to Use Rola-IP Proxies in an Authorized Data Workflow
Rola-IP provides residential, static residential, and other IP proxy routes. Configure the optional proxy only when a different network egress is actually required—for example, to compare how permitted public pages display in different regions or to provide a manageable egress route for an approved data workflow. Rotating residential proxies are suitable for independent short requests, while static residential proxies are more appropriate for sessions that need to keep the same egress IP. When choosing between them, compare region, stability, traffic cost, and the target platform’s rules.
For product overviews, see Rola-IP’s residential proxy and web scraping proxy pages. Those pages describe coverage regions, session modes, and plans; use the account dashboard for the current configuration details.
First use an IP echo service to diagnose the proxy route. Read credentials from a securely supplied environment variable and avoid logging proxy URLs.
The following request configures only the IP echo check. The complete exporter in Code 8 separately passes a Requests session to PRAW and uses ROLA_PROXY_URL, if set, for HTTP(S) proxy routing. If unset it uses a direct route and deliberately ignores inherited proxy environment variables.
Set ROLA_PROXY_URL only when the approved workflow needs a proxy. Use the endpoint and authentication method supplied by your account. For username/password authentication, the placeholder format is http://USERNAME:PASSWORD@HOST:PORT; URL-encode special characters in the username and password. For an IP-allowlisted endpoint, omit the credential component and confirm that the current public IP is allowlisted. Supply live values through a secure environment or secret manager.
PowerShell placeholder:
$env:ROLA_PROXY_URL="http://USERNAME:PASSWORD@HOST:PORT"
Without ROLA_PROXY_URL, Code 8 uses a direct route. Run Code 10 only after configuring the proxy variable.
Code 10. Verify the Rola-IP egress IP
import os
import requests

from ipaddress import ip_address

try:
    proxy = os.environ["ROLA_PROXY_URL"]
    response = requests.get(
        "https://ipinfo.io/json",
        proxies={"http": proxy, "https": proxy}, timeout=15,
    )
    response.raise_for_status()
    print(ip_address(response.json()["ip"]))
except (requests.RequestException, ValueError, KeyError) as exc:
    print("Proxy diagnostic failed:", type(exc).__name__)
    raise SystemExit(1)
For authentication methods, ports, and allowlist configuration, see the English Python proxy integration documentation. For the requests proxy arguments, see Python Requests proxy.
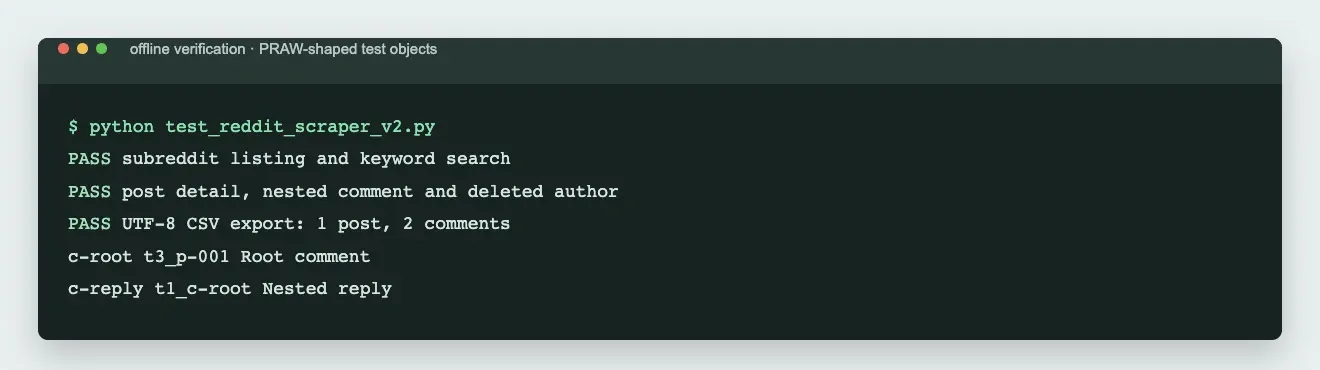
Figure 4. Rola-IP’s Python integration documentation.
Common Reddit Scraping Errors and Retry Handling
| Symptom | Possible cause | First check |
|---|---|---|
| 401 / 403 | Invalid credentials, insufficient permission, or access denied | Check the Reddit application and approved scope; do not blindly switch IPs |
| 429 | Request rate is too high | Stop the run and inspect Retry-After; wait at least that long before a new run. Do not switch IPs to evade the limit |
| 200 but no posts | Challenge page, login page, or changed selectors | Inspect the actual page content and fields rather than relying only on the status code |
| 503 / timeout | Service temporarily unavailable or network-path failure | Allow finite client retries, then inspect sanitized status codes and timings; do not log credentials, proxy URLs, or raw response bodies |
| Proxy 407 | Authentication, allowlist, or port configuration error | Verify the proxy route first with an IP echo service |
| Empty author field | Author names are omitted by default; the account may also be deleted or unavailable | Check whether --include-authors was enabled; retain an empty value when the author is unavailable |
| Fewer comments than expected | Export limits, unexpanded MoreComments, deleted content, or access restrictions |
Check --comments-per-post and --more-limit, then compare accessible content with the export scope |
The exporter does not wrap failed tasks in an additional retry loop. PRAW/prawcore provide their own request and rate-limit handling; the installation command above pins the versions used for offline checks. If an error reaches the script it records the exception type, HTTP status and Retry-After when available, saves partial rows and exits. Do not treat partial CSV files as a complete export. Review the returned delay before restarting after a 429. Request timeouts are 20 seconds; they do not bound all library waits or the whole export.
If access fails because of a network-security restriction rather than Reddit authorization, see the Reddit blocked by network security troubleshooting guide. Do not use a proxy to bypass an API permission decision or a rate limit.
Does limiting exported comments also limit API requests?
No. Slicing comments.list() after expansion limits rows, not the requests already spent expanding MoreComments. Set a finite expansion limit before traversal and record it alongside the export.